Why Generic AI Tools Fail Here
The Stochastic Drift Bottleneck
Paying $2,800/month for idle dedicated A100s destroys margins, while naive serverless Docker images suffer 90-second cold starts and random OOM crashes.
11 · Cloud GPU & MLOps
Sub-second warm starts and autoscaling REST APIs on RunPod, Modal & Replicate.
Executive Overview
Insiyak containerizes ComfyUI and custom diffusion pipelines onto RunPod Serverless, Modal, Replicate, or AWS EKS—baking checkpoints into immutable images or NVMe volumes, minimizing cold-start latency, and exposing HMAC-signed webhook REST APIs.
Why Generic AI Tools Fail Here
Paying $2,800/month for idle dedicated A100s destroys margins, while naive serverless Docker images suffer 90-second cold starts and random OOM crashes.
Insiyak Deterministic Architecture
We strip container layers, pre-warm VRAM snapshots, enforce Zod job schemas, stream outputs directly to S3/Cloudflare R2 via presigned URLs, and emit per-job GPU cost telemetry.
4-Stage Production Workflow
Profile peak memory, model load times, and optimal GPU SKU.
Freeze weights, custom nodes, and Torch runtime into slim layers.
Connect async job queues, R2/S3 uploads, and signed webhooks.
Verify burst concurrency, OOM recovery, and per-call unit cost.
Production Stack
Concrete Handoff Deliverables
Archive Proof
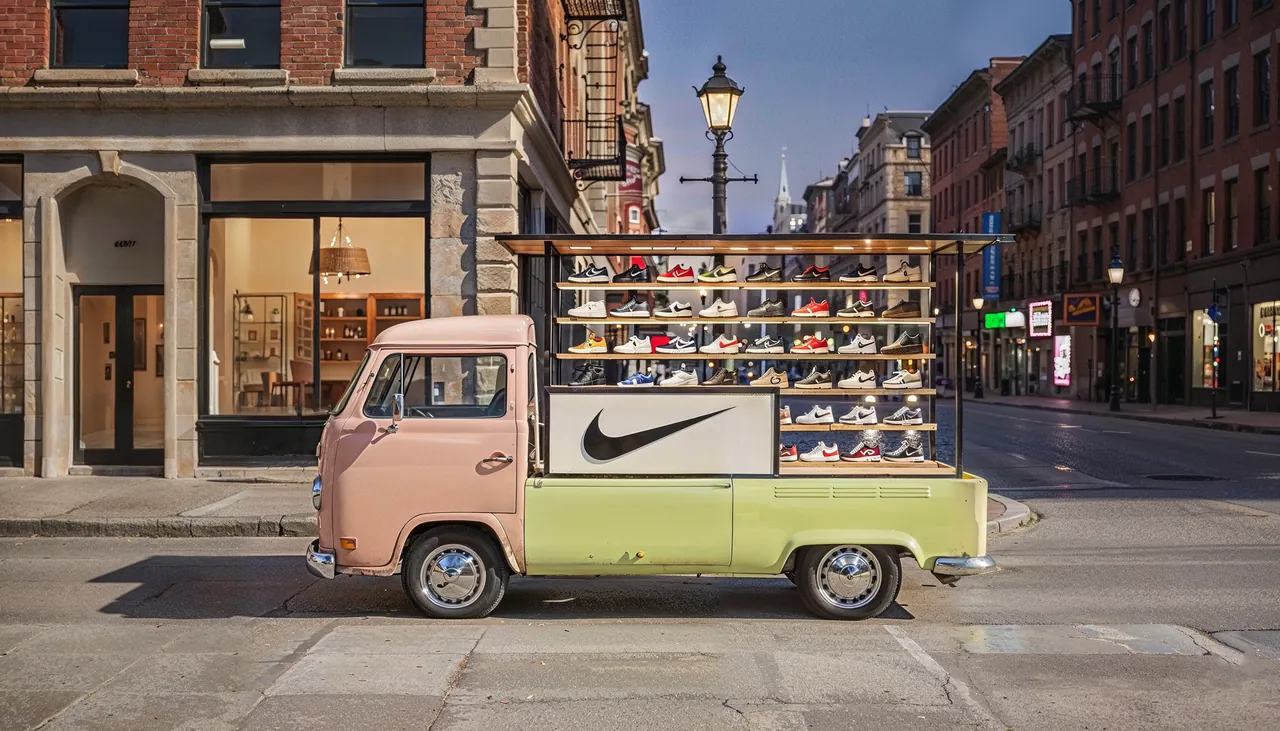
110 commercial vehicle branding mockups generated automatically in minutes.
Technical FAQ
RunPod Serverless (FlashBoot) and Modal lead on cold-start speed and per-second L40S/4090 economics; we benchmark both for your exact graph.
With FlashBoot or Modal memory snapshots, cold starts typically drop from 75+ seconds down to 2–8 seconds.
Yes—we deploy directly into your own RunPod, Modal, Replicate, or AWS organization so you control billing and security.
Related Engineering Guides
RunPod Serverless delivers the lowest raw per-second GPU cost ($0.004–$0.012 per 4K Flux render on RTX 4090/L40S with FlashBoot), Modal offers the best Python-native container developer experience and sub-5s memory snapshots, and Replicate Cog suits rapid public API prototyping at higher volume cost.
Benchmark Your Own Assets in 72 Hours